03/Work, selected
07 / 08

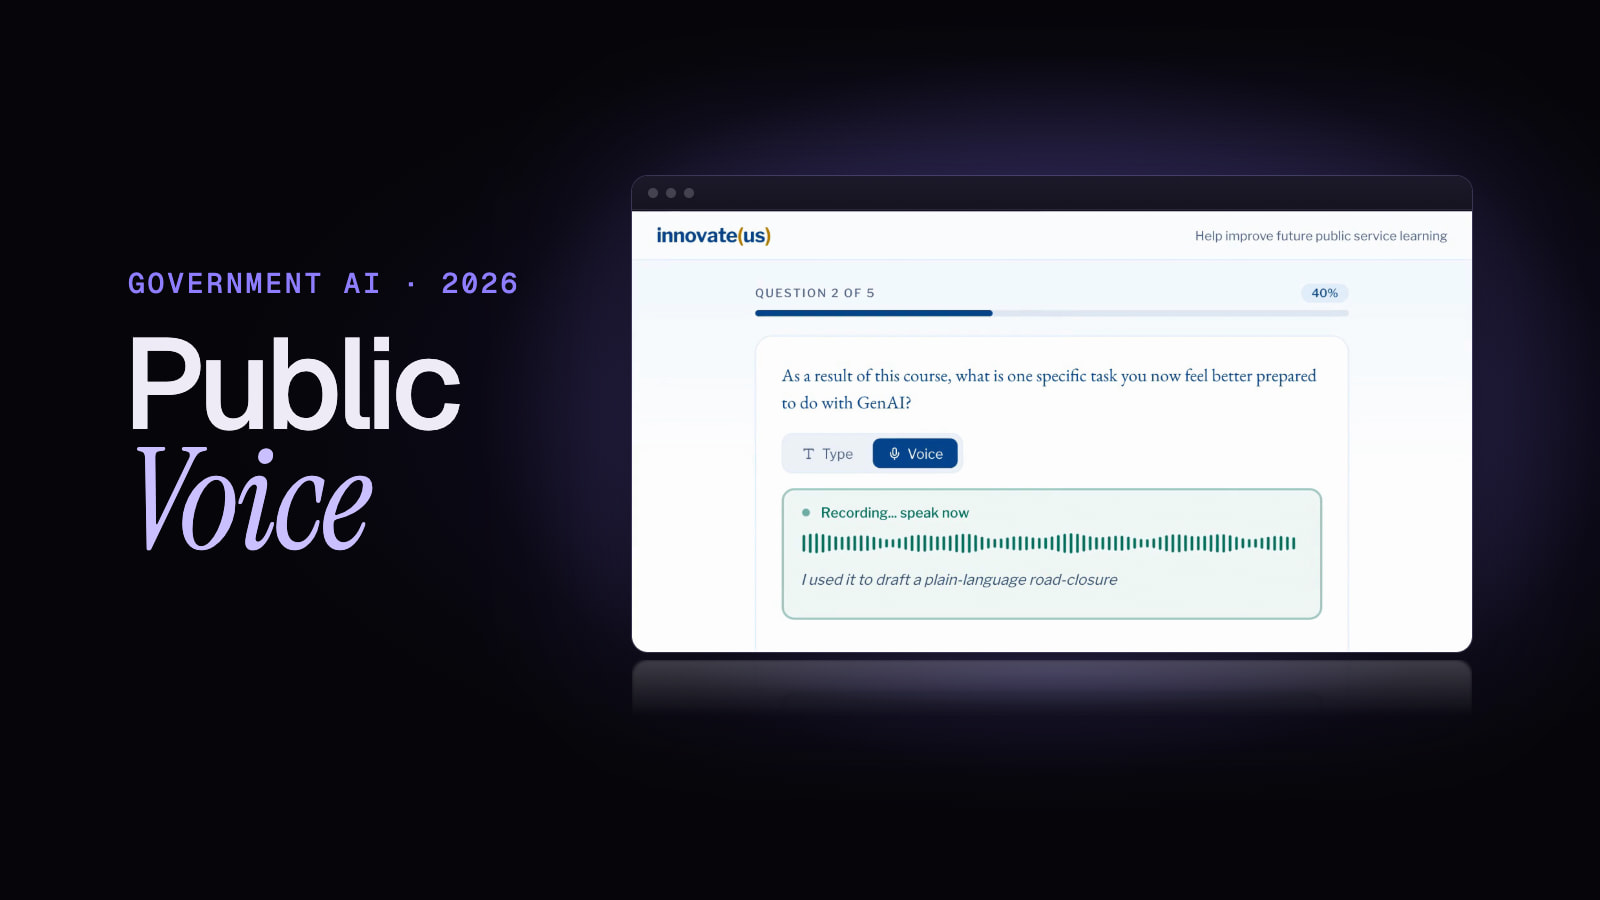
PUBLIC VOICE LAUNCH FILM: TEXT ALTERNATIVE Landscape and vertical cuts share one timeline, 20 seconds, with the same text. Differences in the vertical cut are noted in brackets. Audio: quiet instrumental music and a few soft interface sounds. There is no narration or speech. The "speaking" shown on screen is represented only by an animated waveform and on-screen transcript text. Content flags - ILLUSTRATIVE: the example survey answer, the follow-up question and the Thank you summary are sample content taken from the product’s own demo. The six answers on the organizer dashboard and their grouping into themes are fictional and are labelled "Illustrative" on screen. No real participant data and no usage statistics are shown. - DESIGN TARGET: "About 3 min" is the product’s design target, not a measured result. BEAT BY BEAT 0:00 to 0:02.8 Hook On-screen text: "No login · Speak instead of typing" (shown in capitals). "A survey that listens." ("listens." is in an italic serif). Visual: a dark purple screen with a glowing, constantly moving voice waveform across the middle. The headline slides in at about 1 second. 0:02.8 to 0:05.6 Beat 1, Speak On-screen text: "01 · Speak" and "Answer out loud." Inside the product screen: "innovate(us)"; "Question 2 of 5"; "40%"; "As a result of this course, what is one specific task you now feel better prepared to do with GenAI?"; "Type"; "Voice"; "Start Recording" (briefly); "Recording... speak now"; and a live transcript that appears word by word: "I used it to draft a plain-language road-closure notice for residents". Then "Response Confirmed" (from about 0:05.6). [Landscape only: the browser address bar shows "publicvoice.innovate-us.org/c/generative-ai/survey" and the top bar shows "Help improve future public service learning".] Visual: the survey question screen, rebuilt in a [landscape: browser window, vertical: phone frame] that rises into view and slowly pushes in. A green waveform animates inside the recording box while the transcript fills in. ILLUSTRATIVE sample answer. 0:06.0 to 0:08.6 Beat 2, One smart follow-up On-screen text: "02 · One smart follow-up" and "Asked only when an answer is vague." Inside the product screen: "Follow-up question"; "Nice. About how long would that have taken before, and how long now?"; "Type or speak your answer…", which changes to "Recording... speak now". Visual: the page scrolls and a single follow-up question slides in under the confirmed answer, marked with a yellow dot. A second small green waveform shows the person answering by voice. ILLUSTRATIVE sample question. 0:08.6 to 0:10.9 Beat 3, Done On-screen text: "03 · Done" and "Then it lets you go." Inside the product screen: "Thank you!"; "Your feedback has been submitted. It will help improve future courses for public service professionals."; "What We Heard"; "Planned task"; "Draft plain-language public notices with GenAI." [Landscape only: address bar changes to ".../done".] Visual: the survey screen fades to a thank-you page with a green check and a small summary card showing what the system heard. ILLUSTRATIVE sample summary. 0:10.9 to 0:14.0 Beat 4, Organizer view On-screen text: "04 · Organizer view · Illustrative answers" and "Organizers see what we heard." [Vertical: the label reads "04 · Organizer view".] Inside the product screen: "InnovateUS Dashboard"; "Export Data"; "Top Themes"; "Illustrative". Theme headings: "Drafting", "Plain language", "Public comms". Example answers: "Drafted a road-closure notice"; "Wrote a first draft of a newsletter"; "Rewrote a permit form in plain English"; "Simplified a benefits letter"; "Prepared talking points for a town hall"; "Wrote replies to resident questions". [Landscape only: "Sign Out" button, and a "Responses" list on the left holding the six answers before they move.] Visual: the dashboard appears. The six example answers arrive one at a time and settle under the three theme headings. [Landscape: they slide from a Responses list into the Top Themes card. Vertical: the dashboard is reflowed into a single stacked themes list.] There are no numbers or counts. FICTIONAL, labelled Illustrative. 0:14.3 to 0:17.4 Closing line and proof points On-screen text: "People speak. Organizers hear." ("hear." in italic serif). Four labels appear one by one: "No login", "No stored audio", "English + Spanish", "About 3 min · design target". Visual: large headline on the dark background with the four labels in rounded outlines [landscape: in a row, vertical: stacked] and a faint moving waveform below. "About 3 min" is a design target, not a measurement. 0:17.47 to 0:20.0 End card On-screen text: "Public Voice". "Built with the Burnes Center team · Dhruv Kamalesh Kumar". [Vertical: shown on three lines: "Built with the Burnes Center team", a centered dot, "Dhruv Kamalesh Kumar".] Visual: a small icon of seven vertical bars like a voice waveform, the product name in large type, a thin orange rule, and the credit line in small monospace capitals. A soft bell sounds as the title appears.
01/The problem
Surveys ask too much and hear too little.
After-course surveys return six-word answers. Interviews are rich but too slow to run after every course. InnovateUS needed something in between.
02/What I built
A survey you answer out loud, with one smart follow‑up.
- 01
A no-login link opens a short survey. People answer by voice or text, in English or Spanish, and every question can be skipped.
- 02
When an answer is vague, an AI asks one targeted follow-up, never more than two. Then it extracts the task, the workflow, the outcome and the public benefit.
- 03
Privacy is the product: no stored audio, PII redaction in the backend, and results reviewed at the cohort level.
- 04
It grew from a voice survey prototype I built in July 2025 on OpenAI’s realtime API.
03/Architecture
Voice in, themes out, no recordings kept.
The browser only talks to Next.js, which proxies to FastAPI. The backend redacts PII, asks the model whether an answer is specific enough, stores structured extractions, and feeds a cohort dashboard with exports.
04/Outcomes
Live at InnovateUS.
Live
In production at InnovateUS
Open at publicvoice.innovate-us.org, no login needed.
Third partySource: publicvoice.innovate-us.org
0
Audio recordings stored
Answers are transcribed and personal details are redacted before anything is saved.
From the repo
3 min
Design target to finish a survey
The survey is built to take about three minutes.
From the repo
- Mechanism
A model judges whether each open answer is specific enough. If not, it asks one follow-up, two at most, and both can be skipped. On submit, extraction pulls the task, the workflow, the outcome and the public benefit in the background.
- Privacy
Voice goes through our server to OpenAI’s transcription model and is never written to disk. Redaction runs in three layers (browser pattern match, server pattern match, then an AI pass) and fails closed. The pre-redaction original is not stored.
- Evidence
Private repo
The production repo is private. The 2025 prototype it grew from is public.
06/Stack
Built with
- Next.js 16
- React 19
- Tailwind CSS
- FastAPI
- PostgreSQL
- SQLAlchemy
- OpenAI
- Render
07/In use
The work, up close
08/Links
