03/Work, selected
05 / 08
ABE and One-L
Two AI agents for state procurement, recognized by NASPO in 2025.

What I ownedOwnership: Led the engineering
Joined One‑L in November 2025 and ABE in February 2026, after the 2025 NASPO awards. Since then I lead ABE’s engineering, where I built the quality monitoring and the thumbs-up-to-test-case pipeline; on One‑L I set the direction, with four co-op students on the build.
2NASPO awards for ABE and One‑L, 2025
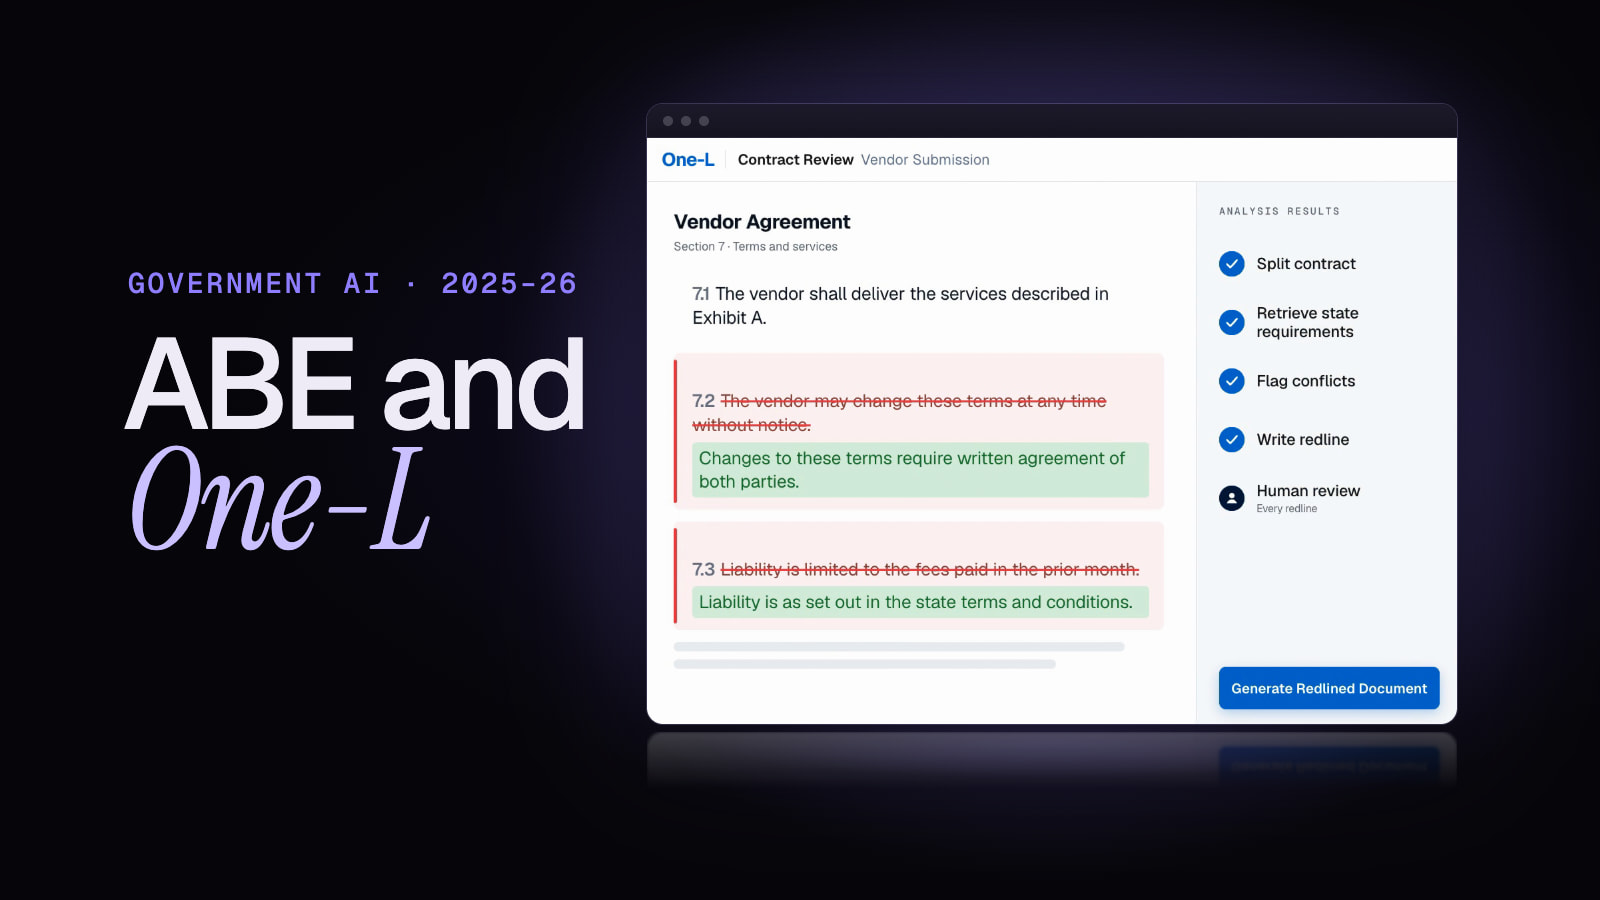
ABE + One‑L: text alternative for the launch film Landscape and vertical cuts tell the same story in the same words. The landscape cut runs 18.0 s and the vertical cut 19.9 s, so each beat lists landscape then vertical timecodes. Audio: soft instrumental music bed and a few quiet interface sounds (clicks, soft thuds, one low bell on the award and one on the end card). No speech and no narration. Style: near-black background with violet light, white type, one italic serif word per scene. Mono labels are set in capitals on screen. A small label "ABE + One‑L" sits in the top-left corner through most of the film. A thin progress line runs along the edge. Illustrative content is flagged below. Nothing in this film is a live product screenshot. BEAT 1: Hook Landscape 0:00 to 0:02.3 | Vertical 0:00 to 0:02.4 On-screen text (verbatim): Massachusetts state procurement Two AI agents for state procurement. Agent 01 / ABE / Assistive Buyer Engine Agent 02 / One‑L / Contract review Visual: the headline rises line by line, with "procurement." in italic serif; two small cards, ABE and One‑L, slide in beside it (landscape) or below it (vertical). BEAT 2: ABE answers a buyer’s question Landscape 0:02.3 to 0:05.6 | Vertical 0:02.4 to 0:06.9 On-screen text (verbatim): Agent 01 ABE Assistive Buyer Engine Answers a buyer’s question, with citations. Illustrative recording Vertical version only, appearing one by one: 1 Confirm scope / 2 Compare vendors / 3 Release the order Visual: a screen recording (sped up) of the ABE chat. A buyer types "How do I make a purchase under a Statewide Contract?", ABE shows a searching state, then streams an answer with three bullets (Confirm scope, Compare vendors, Release the order) and a "3 documents referenced" link. ILLUSTRATIVE: the recording uses a mocked browser frame, not a capture of the production site. BEAT 3: ABE quality loop Landscape 0:05.5 to 0:08.0 | Vertical 0:06.8 to 0:10.2 On-screen text (verbatim): ABE · Quality loop Quality, instrumented. RAGAS evaluation pipeline Faithfulness / Relevancy / Precision / Recall SAMPLE DATA (pill on the top right corner of the screenshot) Sample data, not published results Visual: a screen recording of ABE’s Quality Monitoring page. A "Running evaluation" card shows progress and "Scoring with RAGAS metrics...", then results appear: three score cards and a per-question results table. ILLUSTRATIVE: the scores in the recording are sample data and are not claims made by this film. No evaluation results are published, so the SAMPLE DATA pill stays on the screenshot for the whole beat. BEAT 4: One‑L reviews a contract Landscape 0:08.0 to 0:12.0 | Vertical 0:10.2 to 0:14.4 On-screen text (verbatim): Agent 02 One‑L Flags contract conflicts and writes the redline. 83% Less legal review time Self-reported Five steps, ticked off in turn: Split contract / Retrieve state requirements / Flag conflicts / Write redline / Human review (with the note "Every redline") Sample document text: Vendor Agreement; 7.2 The vendor may change these terms at any time without notice. Replaced by: Changes to these terms require written agreement of both parties. 7.3 Liability is limited to the fees paid in the prior month. Replaced by: Liability is as set out in the state terms and conditions. Conflict (tag on each flagged clause) Illustrative redline (shown on screen) Visual: a contract-review window built in One‑L’s blue and white style. Clauses 7.2 and 7.3 are flagged with a red bar and a Conflict tag, struck through in red, and followed by green replacement wording, while a row of steps fills with ticks and the 83% figure counts up. In the landscape version the steps sit in a panel on the right with a "Generate Redlined Document" button; in the vertical version they are a row of five ticks above the document. ILLUSTRATIVE: the document, clauses and wording are invented samples. BEAT 5: The award Landscape 0:12.0 to 0:14.9 | Vertical 0:14.4 to 0:17.0 On-screen text (verbatim): NASPO · 2025 George Cronin Gold Award and the Academic Collaboration Award Won by Massachusetts OSD with the Burnes Center Visual: centred type on the dark background; the word "Gold" is in italic serif and warm amber, the only warm colour in the film. BEAT 6: End card Landscape 0:14.95 to 0:18.0 | Vertical 0:17.0 to 0:19.9 On-screen text (verbatim): ABE + One‑L Built with the Burnes Center team · Dhruv Kamalesh Kumar Visual: the two names in large white type with a violet plus sign, the credit line beneath in small capitals. No web address.
01/The problem
Procurement runs on rules nobody can keep in their head.
Massachusetts buyers wade through a thicket of purchasing rules, and lawyers redline every vendor contract against state terms by hand. Both jobs are slow and easy to get wrong.
02/What I built
Two agents: one answers buyers, one redlines contracts.
- 01
ABE, the Assistive Buyer Engine, is an agentic RAG chatbot. Claude on Bedrock calls four tools in a loop (knowledge base search, full-document retrieval, metadata and structured spreadsheet queries) and answers with citations.
- 02
One‑L takes a vendor contract through an 11-stage Step Functions workflow. It splits the document, retrieves state requirements, has Claude 4 Sonnet flag conflicts, merges the results and writes a redlined file. A human reviews every redline.
- 03
Both agents won NASPO awards in 2025, before I joined: I picked up One‑L in November 2025 and ABE in February 2026. I own ABE’s quality loop today. A teammate, Ritik Bompilwar, wrote the first RAGAS pipeline in 2025. From February 2026 I built the quality-monitoring platform around it, added the path that turns thumbs-up answers into test cases.
- 04
ABE is now a white-label template. One config file sets the brand, so another agency can rebrand and deploy it from a single file.
- 05
I have set the technical direction for One‑L since November 2025, working with the four Northeastern co-op students on the team.
03/Architecture
Questions get citations. Contracts get redlines.
A question hits the agent loop, Claude calls retrieval tools and answers with citations. Contracts run through the Step Functions redline workflow. Evaluation runs score the answers and alarms watch the system.
A/ABE
B/One-L
04/Outcomes
Two NASPO awards, and lawyers who start from a draft.
2
NASPO awards for ABE and One‑L, 2025
Cronin Gold and Academic Collaboration, won by Massachusetts OSD with the Burnes Center before I joined either project. I now lead ABE’s quality monitoring and One‑L’s direction.
Third partySource: naspo.org
83%
Less legal review time
From my résumé: lawyers review a redline that One‑L has already drafted, instead of marking up each contract by hand. The baseline and sample are not published here.
Self-reported
- Evaluation
Instrumented, no results
A Step Functions pipeline scores each test question on seven RAGAS metrics, including faithfulness and context recall. Test questions are curated, plus thumbs-up answers that an LLM rewrites into Q&A. The judge is the same primary Claude model that writes the answers, so the scores are not cross-family. No results are published here, and the screenshot below is sample data.
- Eval time
One evaluated question takes about 60 to 90 seconds: a full chatbot answer plus six RAGAS judge calls. A run fans out one question per Lambda, three at a time.
- Retrieval
Claude Opus 4.6 answers from a Bedrock Knowledge Base on OpenSearch Serverless (semantic chunking, Titan Embed v2), and Sonnet 4.6 takes the fast jobs. ABE began on Kendra in 2024 and moved off it in September 2024, before my first commit.
- Guardrails
Bedrock Guardrails on the chat path, a web application firewall in front, and Cognito sign-in.
- What broke
- Evals hung as “running”. Large runs passed the 15-minute Lambda limit, and the error handler read the wrong Step Functions path and crashed itself, so the run never left “running”. Now one question per chunk, a real FAILED state, and a Failed chip in the History tab.
- An Excel result overflowed the context window. Tool output is now capped before it reaches the model, and I trimmed the system prompt from about 4,400 to 2,500 tokens.
- Reversed
Retrieval carried a 0.6 score cutoff that looked like a quality gate. Hybrid scores run about 1.3 to 1.6, so it removed nothing. I dropped it and cap chunks per document instead.
06/Stack
Built with
- AWS CDK
- TypeScript
- Python
- Bedrock
- Claude
- OpenSearch Serverless
- Titan Embeddings
- Step Functions
- Lambda
- DynamoDB
- Cognito
- CloudFront
- RAGAS
- React
07/In use
