03/Work, selected
01 / 08

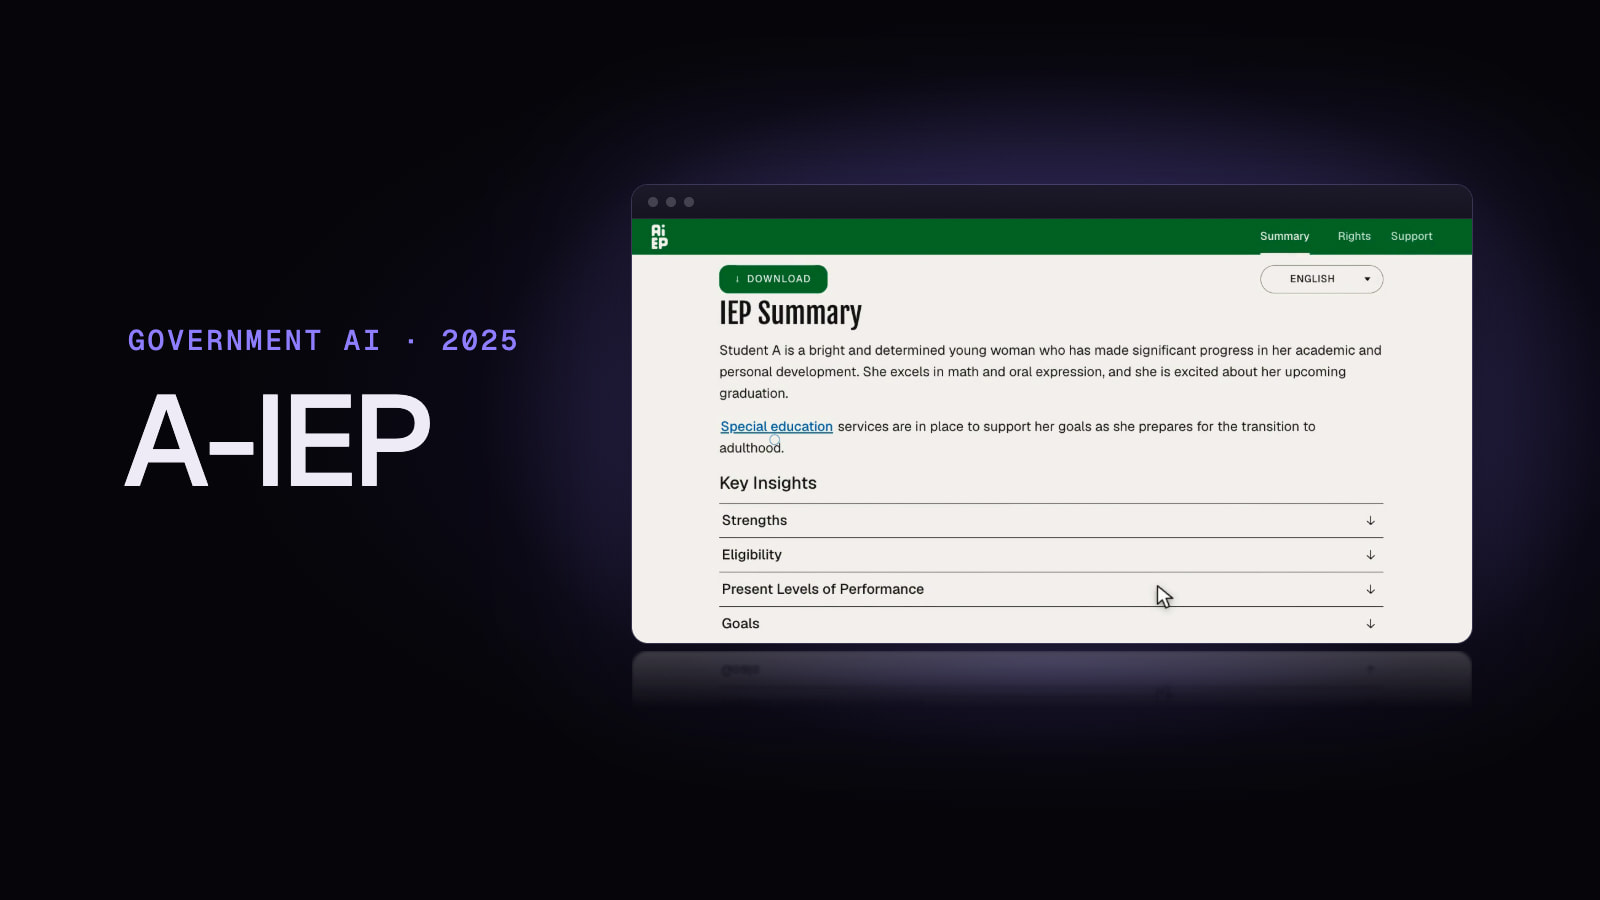
A‑IEP launch film: text alternative Runtime 0:20. Music bed and soft interface sounds only, no narration. Landscape and vertical cuts share one timeline; line breaks differ. Sample content ("Student A") is fictional. Text shown in capitals on screen is written here as it appears. 0:00 to 0:03 The problem On screen: A‑IEP / THE PROBLEM / THE IEP / "Parents often sign it without being able to read it." Visual: A dense wall of special-education jargon (FAPE, LRE, PLAAFP, measurable annual goals) scrolls fast and blurred, then settles dim behind a large white headline; the word "read" is set in an italic serif in pale violet. 0:03 to 0:06 Tap a term On screen: 01 / DEFINITIONS / "Tap any term. Get a plain definition." / In the app: A‑IEP, Summary, DOWNLOAD, ENGLISH, "IEP Summary", the underlined link "Special education", Key Insights, Strengths. Visual: The A‑IEP summary screen rises into a framed window; a pointer taps "Special education" and a Glossary drawer slides in from the right. 0:05 to 0:06 Plain definition (drawer open) On screen: Glossary / Special Education / "Specially designed instruction to meet the unique needs of eligible kids whose educational needs can’t be met through modification of the regular instructional program; provides for a range of options for services, such as pull out programs, special day classes; available to kids enrolled in public schools." Visual: The blue-headed drawer fills the right of the screen with the definition in plain type, then slides away. 0:06 to 0:11 Your own language On screen: 02 / LANGUAGE / "Read it in your own language." / Language menu: English, Español, 中文, Tiếng Việt / Dropdown label changes ENGLISH, ESPAÑOL, TIẾNG VIỆT, 中文 / Page titles "IEP Summary", "Resumen del IEP", "Tóm tắt IEP", "IEP摘要" / Section headings "Key Insights", "Información Clave", "Thông tin chính", "关键信息". Visual: A pointer opens the language dropdown three times and picks Español, Tiếng Việt, then 中文; each time the whole summary (title, paragraph, section headings) swaps into that language. 0:11 to 0:14 Private by design On screen: PRIVACY (03 / PRIVACY) / "Private by design." / SAMPLE IEP, FICTIONAL STUDENT / "Alex Rivera, born May 9, lives at 18 Elm Street and is eligible for services." / "Names and addresses redacted before the model reads it" / "Original upload deleted" Visual: A sample document line appears; violet bars slide over the name and the street address while the birth date stays readable; the document then fades away, and two short lines with small dots confirm what happened. 0:14 to 0:17 Reach On screen: IMPACT (04 / IMPACT) / "375+" IEPS PROCESSED / "200+" FAMILIES IN THE FIRST SAN FRANCISCO PILOT / "Parents co-designed the prompts." Visual: Two very large numbers count up, each with a small caption, above a thin rule and a closing line. 0:17 to 0:20 End card On screen: "A‑IEP" / BUILT BY DHRUV KAMALESH KUMAR Visual: The A‑IEP name in large white type rises into place on the dark violet background, a short violet line draws, and the credit appears below. The music fades out.
01/The problem
Parents were signing plans they couldn’t read.
An Individualized Education Program is the legal document that decides a child’s support. It is dense, full of jargon and usually in English. Parents often sign it without being able to read it.
02/What I built
A pipeline that reads the plan, so parents don’t have to decode it.
- 01
I took the AI-EP prototype from the 2023 to 2024 co-op team and rebuilt it as a production, open source platform.
- 02
A Step Functions pipeline runs OCR, redacts personal information with Comprehend (every name included since the September 2026 change, which reaches production on 9 Oct 2026; dates kept), deletes the original upload, writes a plain-language summary in nine sections, then translates it. OCR is the one step that sees the original page; the models that summarize and translate only ever see redacted text.
- 03
Privacy comes first: every stage catches into a failure handler that purges unredacted artifacts, every durable store is protected from deletion, and infrastructure tests check both.
- 04
Parents helped design it. We showed them the prompts and let their feedback reshape the output. Jargon words open a tap-to-define drawer, and each section points back to the original page.
- 05
Quality is next. In July 2026 I audited the pipeline and found its only automated check on output was a schema check. The evaluation design is written up in the repo: atomic-fact checks, a cross-family judge and a translation judge, projected at about $0.25 to $0.55 per document. The synthetic benchmark behind it is still being built, and no accuracy results are published yet.
03/Architecture
Upload in, plain language out, the original deleted.
Upload, OCR, redact PII, delete the original, summarize into nine sections, translate, finalize. Any failure purges unredacted artifacts.
04/Who sees what
Follow one page through the pipeline.
A made-up IEP excerpt, stepped through the real stages. At each one: which vendor reads the text, and what is on the page when they do.
Fictional sample, not a real student. The replacements apply the redactor’s rules by hand, and how many identifiers it misses is not measured yet. The sample includes a date of birth, a diagnosis and a school name on purpose, to show what the redactor keeps or may miss.
05/Outcomes
Hundreds of plans, four languages.
4
Languages in production
English, Spanish, Vietnamese and Chinese are enabled in production. Arabic, with a right-to-left layout, is built and enabled on dev and staging only.
From the repoSource: github.com
375+
IEPs processed
Plans parents uploaded to read in plain language, in English, Spanish, Vietnamese or Chinese, from about 260 family accounts (July 2026 count).
From the repoSource: github.com
200+
Families in the first San Francisco pilot
Parents co-designed the tool and reported feeling more confident advocating for their children. Reported by the Burnes Center and Reboot Democracy, October 2026.
Employer-reportedSource: rebootdemocracy.ai
100
Test files on main
69 TypeScript and 31 Python test files in the public repo, including the pipeline’s failure-path tests and a Playwright end-to-end suite.
From the repoSource: github.com
- OCR evaluation
Measured, unpublished
The first stage I measured is OCR, on synthetic IEPs (clean, scanned and photographed), scoring digit-bearing facts, checkboxes and invented numbers rather than text similarity. A self-hostable 1B model, LightOnOCR-2, matched production Mistral OCR on facts, numbers and checkboxes and invented no numbers; the only difference was one dropped diacritic in an 8 pt table. A 4-bit build of olmOCR 2 read 0% of checkboxes on clean pages while its text similarity stayed near 97%; the FP8 build read 100%. Quantization, not the model, removed the information parents act on. Runs from 30 Sep and 1 Oct 2026; the results are not published yet.
- Evaluation
Designed, not run
For the summaries themselves, the only automated check is still a schema check: nine sections present, in the right shape. The summary benchmark is a written design, not a result. It scores atomic facts against both the summary and the source, uses a judge from a different model family, and grades each translation with a per-language judge. No accuracy number exists yet, so none is shown.
- Cost
Projected
Judge-based scoring is projected at about $0.25 to $0.55 per document, or $25 to $110 a month at 100 to 200 documents. Those are planning estimates from my cost study, not a bill. A comment in the pipeline’s tests records the median of 100 production and staging runs: 29 seconds to summarize and 24 to translate.
- Who sees what
- Mistral OCR The original page, names included. A no-training enterprise contract limits what Mistral may do with it, not what it receives. The uploaded copy is deleted from Mistral as soon as OCR answers, best effort.
- Comprehend The OCR text, inside our AWS account. It replaces every identifier it finds except dates (names included since the September 2026 change; production release 9 Oct 2026), and fails closed: an error stops the run instead of passing text on. How many identifiers it misses is not measured yet.
- OpenAI The redacted text, to write and translate the summary. Dates (a date of birth included) and diagnoses stay in it by design, and a school name is not specifically handled. The student’s name is a placeholder that the app swaps in when a parent opens the page.
- What broke
- Sign-up failed silently. New and re-created accounts never received their phone code, and nobody noticed for at least a month. I fixed it in July and added a CI gate and post-deploy smoke tests.
- Reversed
My first fix put the child’s name back into the stored summary once processing finished. That turned adding a language into a leak, because it re-reads the stored text. I reversed it the same day: storage keeps a placeholder, and every reader substitutes the name on the way out.
07/Stack
Built with
- AWS CDK
- TypeScript
- Step Functions
- Lambda
- Comprehend
- Cognito
- DynamoDB
- S3
- KMS
- Mistral OCR
- OpenAI GPT-4.1
- React
- Vite
- Playwright
08/In use
